Computer Organization and Design - Chapter 5 - Book solutions - 4th edition - Hennessy, Patterson

Exercise 5.1 In this exercise we consider memory hierarchies for various applications, listed in the following table.
a. Software version control
b. Making phone calls


5.1.1 [10] <5.1> Assuming both client and server are involved in the process, first name the client and server systems. Where can caches be placed to speed up the process?


5.1.2 [10] <5.1> Design a memory hierarchy for the system. Show the typical size and latency at various levels of the hierarchy. What is the relationship between cache size and its access latency?


5.1.3 [15] <5.1> What are the units of data transfers between hierarchies? What is the relationship between the data location, data size, and transfer latency?


5.1.4 [10] <5.1, 5.2> Communication bandwidth and server processing bandwidth are two important factors to consider when designing a memory hierarchy. How can the bandwidths be improved? What is the cost of improving them?


5.1.5 [5] <5.1, 5.8> Now consider multiple clients simultaneously accessing the server. Will such scenarios improve the spatial and temporal locality?


5.1.6 [10] <5.1, 5.8> Give an example of where the cache can provide out­of­date data. How should the cache be designed to mitigate or avoid such issues?


Exercise 5.2
In this exercise we look at memory locality properties of matrix computation. The following code is written in C, where elements within the same row are stored contiguously.
a. for    (I=0;    I<8;    I++)         
 for    (J=0;    J<8000;    J++)
                    A[I][J]=B[I][0]+A[J][I];

b. for    (J=0;    J<8000;    J++)
                for    (I=0;    I<8;    I++)
                    A[I][J]=B[I][0]+A[J][I];


5.2.1 [5] <5.1> How many 32­bit integers can be stored in a 16­byte cache line?


5.2.2 [5] <5.1> References to which variables exhibit temporal locality?


5.2.3 [5] <5.1> References to which variables exhibit spatial locality?
Locality is affected by both the reference order and data layout. The same computation can also be written below in Matlab, which differs from C by contiguously storing matrix elements within the same column.
a. for    I=1:8
            for    J=1:8000
                    A(I,J)=B(I,0)+A(J,I);
            end
    end

b. for    J=1:8000
            for    I=1:8
                    A(I,J)=B(I,0)+A(J,I);
            end
    end


5.2.4 [10] <5.1> How many 16­byte cache lines are needed to store all 32­bit matrix elements being referenced?


5.2.5 [5] <5.1> References to which variables exhibit temporal locality?


5.2.6 [5] <5.1> References to which variables exhibit spatial locality?


Exercise 5.3
Caches are important to providing a high­performance memory hierarchy to processors. Below is a list of 32­bit memory address references, given as word addresses.
a. 3, 180, 43, 2, 191, 88, 190, 14, 181, 44, 186, 253
b. 21, 166, 201, 143, 61, 166, 62, 133, 111, 143, 144, 61


5.3.1 [10] <5.2> For each of these references, identify the binary address, the tag, and the index given a direct­mapped cache with 16 one­word blocks. Also list if each reference is a hit or a miss, assuming the cache is initially empty.


5.3.2 [10] <5.2> For each of these references, identify the binary address, the tag, and the index given a direct­mapped cache with two­word blocks and a total size of 8 blocks. Also list if each reference is a hit or a miss, assuming the cache is initially empty.


5.3.3 [20] <5.2, 5.3> You are asked to optimize a cache design for the given references. There are three direct­mapped cache designs possible, all with a total of 8 words of data: C1 has 1­word blocks, C2 has 2­word blocks, and C3 has 4­word blocks. In terms of miss rate, which cache design is the best? If the miss stall time is 25 cycles, and C1 has an access time of 2 cycles, C2 takes 3 cycles, and C3 takes  5 cycles, which is the best cache design?
There are many different design parameters that are important to a cache’s overall performance. The table below lists parameters for different direct­mapped cache designs.


5.3.4 [15] <5.2> Calculate the total number of bits required for the cache listed in the table, assuming a 32­bit address. Given that total size, find the total size of the closest direct­mapped cache with 16­word blocks of equal size or greater. Explain why the second cache, despite its larger data size, might provide slower performance than the first cache.


5.3.5 [20] <5.2, 5.3> Generate a series of read requests that have a lower miss rate on a 2 KB 2­way set associative cache than the cache listed in the table. Identify one possible solution that would make the cache listed in the table have an equal or lower miss rate than the 2 KB cache. Discuss the advantages and disadvantages of such a solution.


5.3.6 [15] <5.2> The formula shown on page 457 shows the typical method to index a direct­mapped cache, specifically (Block address) modulo (Number of blocks in the cache). Assuming a 32­bit address and 1024 blocks in the cache, consider a different indexing function, specifically (Block address[31:27] XOR Block address[26:22]). Is it possible to use this to index a direct­mapped cache? If so, explain why and discuss any changes that might need to be made to the cache. If it is not possible, explain why.


Exercise 5.4
For a direct­mapped cache design with a 32­bit address, the following bits of the address are used to access the cache.


5.4.1 [5] <5.2> What is the cache line size (in words)?

5.4.2 [5] <5.2> How many entries does the cache have?


5.4.3 [5] <5.2> What is the ratio between total bits required for such a cache implementation over the data storage bits?
Starting from power on, the following byte­addressed cache references are recorded.
Address 0 4 16 132 232 160 1024 30 140 3100 180 2180

5.4.4 [10] <5.2> How many blocks are replaced?


5.4.5 [10] <5.2> What is the hit ratio?
 

5.4.6 [20] <5.2> List the final state of the cache, with each valid entry represented as a record of <index, tag, data>.


Exercise 5.5
Recall that we have two write policies and write allocation policies, and their combinations can be implemented either in L1 or L2 cache.


5.5.1 [5] <5.2, 5.5> Buffers are employed between different levels of memory hierarchy to reduce access latency. For this given configuration, list the possible buffers needed between L1 and L2 caches, as well as L2 cache and memory.


5.5.2 [20] <5.2, 5.5> Describe the procedure of handling an L1 write­miss, considering the component involved and the possibility of replacing a dirty block.


5.5.3 [20] <5.2, 5.5> For a multilevel exclusive cache (a block can only reside in one of the L1 and L2 caches), configuration, describe the procedure of handling an L1 write­miss, considering the component involved and the possibility of replacing a dirty block.
Consider the following program and cache behaviors.


5.5.4 [5] <5.2, 5.5> For a write­through, write­allocate cache, what are the minimum read and write bandwidths (measured by byte per cycle) needed to achieve a CPI of 2?


5.5.5 [5] <5.2, 5.5> For a write­back, write­allocate cache, assuming 30% of replaced data cache blocks are dirty, what are the minimal read and write bandwidths needed for a CPI of 2?


5.5.6 [5] <5.2, 5.5> What are the minimal bandwidths needed to achieve the performance of CPI=1.5?


Exercise 5.6
Media applications that play audio or video files are part of a class of workloads called “streaming” workloads; i.e., they bring in large amounts of data but do not reuse much of it. Consider a video streaming workload that accesses a 512 KB working set sequentially with the following address stream:
0, 2, 4, 6, 8, 10, 12, 14, 16, …


5.6.1 [5] <5.5, 5.3> Assume a 64 KB direct­mapped cache with a 32­byte line. What is the miss rate for the address stream above? How is this miss rate sensitive to the size of the cache or the working set? How would you categorize the misses this workload is experiencing, based on the 3C model?


5.6.2 [5] <5.5, 5.1> Re­compute the miss rate when the cache line size is 16 bytes, 64 bytes, and 128 bytes. What kind of locality is this workload exploiting?


5.6.3 [10] <5.10> “Prefetching” is a technique that leverages predictable address patterns to speculatively bring in additional cache lines when a particular cache line is accessed. One example of prefetching is a stream buffer that prefetches sequentially adjacent cache lines into a separate buffer when a particular cache line is brought in. If the data is found in the prefetch buffer, it is considered as a hit and moved into the cache and the next cache line is prefetched. Assume a two­entry stream buffer and assume that the cache latency is such that a cache line can be loaded before the computation on the previous cache line is completed. What is the miss rate for the address stream above?
Cache block size (B) can affect both miss rate and miss latency. Assuming a 1­CPI machine with an average of 1.35 references (both instruction and data) per  instruction, help find the optimal block size given the following miss rates for various block sizes.


5.6.4 [10] <5.2> What is the optimal block size for a miss latency of 20×B cycles?


5.6.5 [10] <5.2> What is the optimal block size for a miss latency of 24+B cycles?


5.6.6 [10] <5.2> For constant miss latency, what is the optimal block size?


Exercise 5.7
In this exercise, we will look at the different ways capacity affects overall performance. In general, cache access time is proportional to capacity. Assume that main memory accesses take 70 ns and that memory accesses are 36% of all instructions. The following table shows data for L1 caches attached to each of two processors, P1 and P2.


5.7.1 [5] <5.3> Assuming that the L1 hit time determines the cycle times for P1 and P2, what are their respective clock rates?


5.7.2 [5] <5.3> What is the AMAT for P1 and P2?


5.7.3 [5] <5.3> Assuming a base CPI of 1.0 without any memory stalls, what is the total CPI for P1 and P2? Which processor is faster?
For the next three problems, we will consider the addition of an L2 cache to P1 to presumably make up for its limited L1 cache capacity. Use the L1 cache capacities and hit times from the previous table when solving these problems. The L2 miss rate indicated is its local miss rate.


5.7.4 [10] <5.3> What is the AMAT for P1 with the addition of an L2 cache? Is the AMAT better or worse with the L2 cache?


5.7.5 [5] <5.3> Assuming a base CPI of 1.0 without any memory stalls, what is the total CPI for P1 with the addition of an L2 cache?


5.7.6 [10] <5.3> Which processor is faster, now that P1 has an L2 cache? If P1 is faster, what miss rate would P2 need in its L1 cache to match P1’s performance? If P2 is faster, what miss rate would P1 need in its L1 cache to match P2’s performance?


Exercise 5.8
This exercise examines the impact of different cache designs, specifically comparing associative caches to the direct­mapped caches from Section 5.2. For these exercises, refer to the table of address streams shown in Exercise 5.3.

5.8.1 [10] <5.3> Using the references from Exercise 5.3, show the final cache contents for a three­way set associative cache with two­word blocks and a total size of 24 words. Use LRU replacement. For each reference identify the index bits, the tag bits, the block offset bits, and if it is a hit or a miss.


5.8.2 [10] <5.3> Using the references from Exercise 5.3, show the final cache contents for a fully associative cache with one­word blocks and a total size of 8 words. Use LRU replacement. For each reference identify the index bits, the tag bits, and if it is a hit or a miss.


5.8.3 [15] <5.3> Using the references from Exercise 5.3, what is the miss rate for a fully associative cache with two­word blocks and a total size of 8 words, using LRU replacement? What is the miss rate using MRU (most recently used) replacement? Finally what is the best possible miss rate for this cache, given any replacement policy?
Multilevel caching is an important technique to overcome the limited amount of space that a first level cache can provide while still maintaining its speed. Consider a processor with the following parameters:


5.8.4 [10] <5.3> Calculate the CPI for the processor in the table using: 1) only a first level cache, 2) a second level direct­mapped cache, and 3) a second level eightway set associative cache. How do these numbers change if main memory access time is doubled? If it is cut in half?


5.8.5 [10] <5.3> It is possible to have an even greater cache hierarchy than two levels. Given the processor above with a second level, direct­mapped cache, a designer wants to add a third level cache that takes 50 cycles to access and will reduce the global miss rate to 1.3%. Would this provide better performance? In general, what are the advantages and disadvantages of adding a third level cache?


5.8.6 [20] <5.3> In older processors such as the Intel Pentium or Alpha 21264, the second level of cache was external (located on a different chip) from the main processor and the first level cache. While this allowed for large second level caches, the latency to access the cache was much higher, and the bandwidth was typically lower because the second level cache ran at a lower frequency. Assume a 512 KB offchip second level cache has a global miss rate of 4%. If each additional 512 KB of cache lowered global miss rates by 0.7%, and the cache had a total access time of 50 cycles, how big would the cache have to be to match the performance of the second level direct­mapped cache listed in the table? Of the eight­way set associative cache?


Exercise 5.9
For a high­performance system such as a B­tree index for a database, the page size is determined mainly by the data size and disk performance. Assume that on average a B­tree index page is 70% full with fix­sized entries. The utility of a page is its B­tree depth, calculated as log2(entries). The following table shows that for 16­byte entries, and a 10­year­old disk with a 10 ms latency and 10 MB/s transfer rate, the optimal page size is 16K.


5.9.1 [10] <5.4> What is the best page size if entries now become 128 bytes?


5.9.2 [10] <5.4> Based on 5.9.1, what is the best page size if pages are half full?


5.9.3 [20] <5.4> Based on 5.9.2, what is the best page size if using a modern disk with a 3 ms latency and 100 MB/s transfer rate? Explain why future servers are likely to have larger pages.

Keeping “frequently used” (or “hot”) pages in DRAM can save disk accesses, but how do we determine the exact meaning of “frequently used” for a given system? Data engineers use the cost ratio between DRAM and disk access to quantify the reuse time threshold for hot pages. The cost of a disk access is $Disk /accesses_per_ sec, while the cost to keep a page in DRAM is $DRAM_MB/page_size. The typical DRAM and disk costs and typical database page sizes at several time points are listed below:


5.9.4 [10] <5.1, 5.4> What are the reuse time thresholds for these three technology generations?


5.9.5 [10] <5.4> What are the reuse time thresholds if we keep using the same 4K page size? What’s the trend here?


5.9.6 [20] <5.4> What other factors can be changed to keep using the same page size (thus avoiding software rewrite)? Discuss their likeliness with current technology and cost trends.


Exercise 5.10
As described in Section 5.4, virtual memory uses a page table to track the mapping of virtual addresses to physical addresses. This exercise shows how this table must be updated as addresses are accessed. The following table is a stream of virtual addresses as seen on a system. Assume 4 KB pages, a 4­entry fully associative TLB, and true LRU replacement. If pages must be brought in from disk, increment the next largest page number.


5.10.1 [10] <5.4> Given the address stream in the table, and the initial TLB and page table states shown above, show the final state of the system. Also list for each reference if it is a hit in the TLB, a hit in the page table, or a page fault.


5.10.2 [15] <5.4> Repeat Exercise 5.10.1, but this time use 16 KB pages instead of 4 KB pages. What would be some of the advantages of having a larger page size? What are some of the disadvantages?


5.10.3 [15] <5.3, 5.4> Show the final contents of the TLB if it is 2­way set associative. Also show the contents of the TLB if it is direct mapped. Discuss the importance of having a TLB to high performance. How would virtual memory accesses be handled if there were no TLB?
There are several parameters that impact the overall size of the page table. Listed below are several key page table parameters.


5.10.4 [5] <5.4> Given the parameters in the table above, calculate the total page table size for a system running 5 applications that utilize half of the memory available.
 

5.10.5 [10] <5.4> Given the parameters in the table above, calculate the total page table size for a system running 5 applications that utilize half of the memory available, given a two level page table approach with 256 entries. Assume each entry of the main page table is 6 bytes. Calculate the minimum and maximum amount of memory required.


5.10.6 [10] <5.4> A cache designer wants to increase the size of a 4 KB virtually indexed, physically tagged cache. Given the page size listed in the table above, is it possible to make a 16 KB direct­mapped cache, assuming 2 words per block? How would the designer increase the data size of the cache?


Exercise 5.11
In this exercise, we will examine space/time optimizations for page tables. The following table shows parameters of a virtual memory system.
5.11.1 [10] <5.4> For a single­level page table, how many page table entries (PTEs) are needed? How much physical memory is needed for storing the page table?


5.11.2 [10] <5.4> Using a multilevel page table can reduce the physical memory consumption of page tables, by only keeping active PTEs in physical memory. How many levels of page tables will be needed in this case? And how many memory references are needed for address translation if missing in TLB?


5.11.3 [15] <5.4> An inverted page table can be used to further optimize space and time. How many PTEs are needed to store the page table? Assuming a hash table implementation, what are the common case and worst case numbers of memory references needed for servicing a TLB miss?
The following table shows the contents of a 4­entry TLB.


5.11.4 [5] <5.4> Under what scenarios would entry 2’s valid bit be set to zero?


5.11.5 [5] <5.4> What happens when an instruction writes to VA page 30? When would a software managed TLB be faster than a hardware managed TLB?


5.11.6 [5] <5.4> What happens when an instruction writes to VA page 200?


Exercise 5.12
In this exercise, we will examine how replacement policies impact miss rate.  Assume a 2­way set associative cache with 4 blocks. You may find it helpful to draw a table like those found on page 482 to solve the problems in this exercise, as demonstrated below on the address sequence “0, 1, 2, 3, 4.”


The following table shows address sequences.
Address Sequence
a. 0, 2, 4, 8, 10, 12, 14, 16, 0
b. 1, 3, 5, 1, 3, 1, 3, 5, 3


5.12.1 [5] <5.3, 5.5> Assuming an LRU replacement policy, how many hits does this address sequence exhibit?


5.12.2 [5] <5.3, 5.5> Assuming an MRU (most recently used) replacement policy, how many hits does this address sequence exhibit?


5.12.3 [5] <5.3, 5.5> Simulate a random replacement policy by flipping a coin. For example, “heads” means to evict the first block in a set and “tails” means to evict the second block in a set. How many hits does this address sequence exhibit?


5.12.4 [10] <5.3, 5.5> Which address should be evicted at each replacement to maximize the number of hits? How many hits does this address sequence exhibit if you follow this “optimal” policy?


5.12.5 [10] <5.3, 5.5> Describe why it is difficult to implement a cache replacement policy that is optimal for all address sequences.


5.12.6 [10] <5.3, 5.5> Assume you could make a decision upon each memory reference whether or not you want the requested address to be cached. What impact could this have on miss rate?


Exercise 5.13
To support multiple virtual machines, two levels of memory virtualization are needed. Each virtual machine still controls the mapping of virtual address (VA) to physical address (PA), while the hypervisor maps the physical address (PA) of each virtual machine to the actual machine address (MA). To accelerate such mappings, a software approach called “shadow paging” duplicates each virtual machine’s page tables in the hypervisor, and intercepts VA to PA mapping changes to keep both copies consistent. To remove the complexity of shadow page tables, a hardware approach called nested page table (or extended page table) explicitly supports two classes of page tables (VA⇨PA and PA⇨MA) and can walk such tables purely in hardware. Consider the following sequence of operations:
(1) Create process; (2) TLB miss; (3) page fault; (4) context switch;


5.13.1 [10] <5.4, 5.6> What would happen for the given operation sequence for shadow page table and nested page table, respectively?


5.13.2 [10] <5.4, 5.6> Assuming an x86­based 4­level page table in both guest and nested page table, how many memory references are needed to service a TLB miss for native vs. nested page table?


5.13.3 [15] <5.4, 5.6> Among TLB miss rate, TLB miss latency, page fault rate, and page fault handler latency, which metrics are more important for shadow page table? Which are important for nested page table?
The following table shows parameters for a shadow paging system.


5.13.4 [10] <5.6> For a benchmark with native execution CPI of 1, what are the CPI numbers if using shadow page tables vs. NPT (assuming only page table virtualization overhead)?


5.13.5 [10] <5.6> What techniques can be used to reduce page table shadowing induced overhead?


5.13.6 [10] <5.6> What techniques can be used to reduce NPT induced overhead?


Exercise 5.14

One of the biggest impediments to widespread use of virtual machines is the performance overhead incurred by running a virtual machine. The table below lists various performance parameters and application behavior.


5.14.1 [10] <5.6> Calculate the CPI for the system listed above assuming that there are no accesses to I/O. What is the CPI if the VMM performance impact doubles? If it is cut in half? If a virtual machine software company wishes to obtain a 10% performance degradation, what is the longest possible penalty to trap to the VMM?


5.14.2 [10] <5.6> I/O accesses often have a large impact on overall system performance. Calculate the CPI of a machine using the performance characteristics above, assuming a non­virtualized system. Calculate the CPI again, this time using a virtualized system. How do these CPIs change if the system has half the I/O accesses? Explain why I/O bound applications have a smaller impact from virtualization.


5.14.3 [30] <5.4, 5.6> Compare and contrast the ideas of virtual memory and virtual machines. How do the goals of each compare? What are the pros and cons of each? List a few cases where virtual memory is desired, and a few cases where virtual machines are desired.
 

5.14.4 [20] <5.6> Section 5.6 discusses virtualization under the assumption that the virtualized system is running the same ISA as the underlying hardware. However, one possible use of virtualization is to emulate non­native ISAs. An example of this is QEMU, which emulates a variety of ISAs such as MIPS, SPARC, and PowerPC. What are some of the difficulties involved in this kind of virtualization? Is it possible for an emulated system to run faster than on its native ISA?


Exercise 5.15

In this exercise, we will explore the control unit for a cache controller for a processor with a write buffer. Use the finite state machine found in Figure 5.34 as a starting point for designing your own finite state machines. Assume that the cache controller is for the simple direct­mapped cache described on page 529, but you will add a write buffer with a capacity of one block. Recall that the purpose of a write buffer is to serve as temporary storage so that the processor doesn’t have to wait for two memory accesses on a dirty miss. Rather than writing back the dirty block before reading the new block, it buffers the dirty block and immediately begins reading the new block. The dirty block can then be written to main memory while the processor is working.
5.15.1 [10] <5.5, 5.7> What should happen if the processor issues a request that hits in the cache while a block is being written back to main memory from the write buffer?


5.15.2 [10] <5.5, 5.7> What should happen if the processor issues a request that misses in the cache while a block is being written back to main memory from the write buffer?


5.15.3 [30] <5.5, 5.7> Design a finite state machine to enable the use of a write buffer.


Exercise 5.16
Cache coherence concerns the views of multiple processors on a given cache block. The following table shows two processors and their read/write operations on two different words of a cache block X (initially X[0] = X[1] = 0).


5.16.1 [15] <5.8> List the possible values of the given cache block for a correct cache coherence protocol implementation. List at least one more possible value of the block if the protocol doesn’t ensure cache coherency.


5.16.2 [15] <5.8> For a snooping protocol, list a valid operation sequence on each processor/cache to finish the above read/write operations.


5.16.3 [10] <5.8> What are the best­case and worst­case numbers of cache misses needed to execute the listed read/write instructions?
Memory consistency concerns the views of multiple data items. The following table shows two processors and their read/write operations on different cache blocks (A and B initially 0).


5.16.4 [15] <5.8> List the possible values of C and D for an implementation that ensures both consistency assumptions on page 538.


5.16.5 [15] <5.8> List at least one more possible pair of values for C and D if such assumptions are not maintained.


5.16.6 [15] <5.2, 5.8> For various combinations of write policies and write allocation policies, which combinations make the protocol implementation simpler?


Exercise 5.17
Both Barcelona and Nehalem are chip multiprocessors (CMPs), having multiple cores and their caches on a single chip. CMP on­chip L2 cache design has interesting trade­offs. The following table shows the miss rates and hit latencies for two benchmarks with private vs. shared L2 cache designs. Assume L1 cache misses once every 32 instructions.


5.17.1 [15] <5.10> Which cache design is better for each of these benchmarks? Use data to support your conclusion.


5.17.2 [15] <5.10> Shared cache latency increases with the CMP size. Choose the best design if the shared cache latency doubles. Off­chip bandwidth becomes the bottleneck as the number of CMP cores increases. Choose the best design if offchip memory latency doubles.


5.17.3 [10] <5.10> Discuss the pros and cons of shared vs. private L2 caches for both single­threaded, multi­threaded, and multiprogrammed workloads, and reconsider them if having on­chip L3 caches.


 5.17.4 [15] <5.10> Assume both benchmarks have a base CPI of 1 (ideal L2 cache). If having non­blocking cache improves the average number of concurrent L2 misses from 1 to 2, how much performance improvement does this provide over a shared L2 cache? How much improvement can be achieved over private L2?


5.17.5 [10] <5.10> Assume new generations of processors double the number of cores every 18 months. To maintain the same level of per­core performance, how much more off­chip memory bandwidth is needed for a 2012 processor?


5.17.6 [15] <5.10> Consider the entire memory hierarchy. What kinds of optimizations can improve the number of concurrent misses?


Exercise 5.18
In this exercise we show the definition of a web server log and examine code optimizations to improve log processing speed. The data structure for the log is defined as follows:
struct    entry
    {      
      int      srcIP;
                //    remote    IP    address
            char    URL[128];    //    request    URL    (e.g.,    “GET    index.html”)
           long    long    refTime;        //    reference    time
                int        status;            //    connection    status
            char    browser[64];    //    client    browser    name  
}    log    [NUM_ENTRIES];


Some processing functions on a log are:
a. topK_sourceIP    (int    hour);
b. browser_histogram    (int    srcIP);    //    browsers    of    a    given    IP


5.18.1 [5] <5.11> Which fields in a log entry will be accessed for the given log processing function? Assuming 64­byte cache blocks and no prefetching, how many cache misses per entry does the given function incur on average?


5.18.2 [10] <5.11> How can you reorganize the data structure to improve cache utilization and access locality? Show your structure definition code.


5.18.3 [10] <5.11> Give an example of another log processing function that would prefer a different data structure layout. If both functions are important, how would you rewrite the program to improve the overall performance? Supplement the discussion with code snippet and data.
For the problems below, use data from “Cache Performance for SPEC CPU2000 Benchmarks” (http://www.cs.wisc.edu/multifacet/misc/spec2000cache­data/) for the pairs of benchmarks shown in the following table.
a. Mesa / gcc
b. mcf / swim


5.18.4 [10] <5.11> For 64 KB data caches with varying set associativities, what are the miss rates broken down by miss types (cold, capacity, and conflict misses) for each benchmark?


5.18.5 [10] <5.11> Select the set associativity to be used by a 64 KB L1 data cache shared by both benchmarks. If the L1 cache has to be directly mapped, select the set associativity for the 1 MB L2 cache.


5.18.6 [20] <5.11> Give an example in the miss rate table where higher set associativity actually increases miss rate. Construct a cache configuration and reference stream to demonstrate this.


Computer Organization and Design - Chapter 4 - Book solutions - 4th edition - Hennessy, Patterson

Exercise 4.1 
Different instructions utilize different hardware blocks in the basic single-cycle  implementation. The next three problems in this exercise refer to the following  instruction:


4.1.1 [5] <4.1> What are the values of control signals generated by the control in  Figure 4.2 for this instruction?


4.1.2 [5] <4.1> Which resources (blocks) perform a useful function for this  instruction?


4.1.3 [10] <4.1> Which resources (blocks) produce outputs, but their outputs  are not used for this instruction? Which resources produce no outputs for this  instruction?

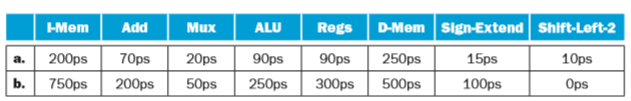
Different execution units and blocks of digital logic have different latencies (time  needed to do their work). In Figure 4.2 there are seven kinds of major blocks. Latencies of blocks along the critical (longest-latency) path for an instruction determine  the minimum latency of that instruction. For the remaining three problems in this  exercise, assume the following resource latencies:


Get 4.1.3 exercise solution 


4.1.4 [5] <4.1> What is the critical path for an MIPS AND instruction?
4.1.5 [5] <4.1> What is the critical path for an MIPS load (LD) instruction?
4.1.6 [10] <4.1> What is the critical path for an MIPS BEQ instruction?


Exercise 4.2 
The basic single-cycle MIPS implementation in Figure 4.2 can only implement  some instructions. New instructions can be added to an existing ISA, but the decision whether or not to do that depends, among other things, on the cost and complexity such an addition introduces into the processor datapath and control. The  first three problems in this exercise refer to this new instruction:

4.2.1 [10] <4.1> Which existing blocks (if any) can be used for this instruction?
4.2.2 [10] <4.1> Which new functional blocks (if any) do we need for this  instruction?
4.2.3 [10] <4.1> What new signals do we need (if any) from the control unit to  support this instruction?
When  processor  designers  consider  a  possible  improvement  to  the  processor  datapath, the decision usually depends on the cost/performance trade-off. In the    following three problems, assume that we are starting with a datapath from Figure  4.2, where I-Mem, Add, Mux, ALU, Regs, D-Mem, and Control blocks have latencies of 400ps, 100ps, 30ps, 120ps, 200ps, 350ps, and 100ps, respectively, and costs of  1000, 30, 10, 100, 200, 2000, and 500, respectively. The remaining three problems in  this exercise refer to the following processor improvement:


4.2.4 [10] <4.1> What is the clock cycle time with and without this improvement?
4.2.5 [10] <4.1> What is the speedup achieved by adding this improvement?
4.2.6 [10] <4.1> Compare the cost/performance ratio with and without this  improvement.


Exercise 4.3 

Problems in this exercise refer to the following logic block:
 
4.3.1 [5] <4.1, 4.2> Does this block contain logic only, flip-flops only, or both?
4.3.2 [20] <4.1, 4.2> Show how this block can be implemented. Use only AND,  OR, NOT, and D Flip-Flops.


4.3.3 [10] <4.1, 4.2> Repeat Problem 4.3.2, but the AND and OR gates you use  must all be 2-input gates.
Cost and latency of digital logic depends on the kinds of basic logic elements  (gates) that are available and on the properties of these gates. The remaining three  problems in this exercise refer to these gates, latencies, and costs:


4.3.4 [5] <4.1, 4.2> What is the latency of your implementation from 4.3.2?
4.3.5 [5] <4.1, 4.2> What is the cost of your implementation from 4.3.2?
4.3.6 [20] <4.1, 4.2> Change your design to minimize the latency, then to minimize the cost.
Compare the cost and latency of these two optimized designs.


Exercise 4.4 

When implementing a logic expression in digital logic, one must use the available  logic gates to implement an operator for which a gate is not available. Problems in  this exercise refer to the following logic expressions:

4.4.1 [5] <4.2> Implement the logic for the Control signal 1. Your circuit should  directly implement the given expression (do not reorganize the expression to “optimize” it), using NOT
 gates and 2-input AND, OR, and XOR gates.
4.4.2 [10] Assuming that all gates have equal latencies, what is the length (in  gates) of the critical path in your circuit from 4.4.1?
4.4.3 [10] <4.2> When multiple logic expressions are implemented, it is possible  to reduce implementation cost by using the same signals in more than one expression. Repeat 4.4.1, but implement both Control signal 1 and Control signal 2, and  try to “share” circuitry between expressions whenever possible.
For the remaining three problems in this exercise, we assume that the following basic  digital logic elements are available, and that their latency and cost are as follows:


4.4.4 [10] <4.2> What is the length of the critical path in your circuit from 4.4.3?

4.4.5 [10] <4.2> What is the cost of your circuit from 4.4.3?


4.4.6 [10] <4.2> What fraction of the cost was saved in your circuit from 4.4.3 by  implementing these two control signals together instead of separately?


Exercise 4.5 
The goal of this exercise is to help you familiarize yourself with the design and  operation of sequential logical circuits. Problems in this exercise refer to this ALU  operation:
ALU Operation
a. Add (X+Y) 

b. Subtract-one (X–1) in 2’s complement
4.5.1 [20] <4.2> Design a circuit with 1-bit data inputs and a 1-bit data output  that accomplishes this operation serially, starting with the least-significant bit. In a  serial implementation, the circuit is processing input operands bit by bit, generating output bits one by one. For example, a serial AND circuit is simply an AND  gate; in cycle N we give it the Nth bit from each of the operands and we get the Nth  bit of the result. In addition to data inputs, the circuit has a Clk (clock) input and  a “Start” input that is set to 1 only in the very first cycle of the operation. In your  design, you can use D Flip-Flops and NOT, AND, OR, and XOR gates.

Get 4.5.1 exercise solution
4.5.2 [20] <4.2> Repeat 4.5.1, but now design a circuit that accomplishes this  operation 2 bits at a time. In the rest of this exercise, we assume that the following basic digital logic elements  are available, and that their latency and cost are as follows:


The time given for a D-element is its setup time. The data input of a flip-flop must  have the correct value one setup-time before the clock edge (end of clock cycle)  that stores that value into the flip-flop.

4.5.3 [10] <4.2> What is the cycle time for the circuit you designed in 4.5.1? How  long does it take to perform the 32-bit operation?

4.5.4 [10] <4.2> What is the cycle time for the circuit you designed in 4.5.2?  What is the speedup achieved by using this circuit instead of the one from 4.5.1 for  a 32-bit operation?


4.5.5 [10] <4.2> Compute the cost for the circuit you designed in 4.5.1, and then  for the circuit you designed in 4.5.2.
4.5.6 [5]  <4.2>  Compare  cost/performance  ratios  for  the  two  circuits  you  designed in 4.5.1 and 4.5.2. For this problem, performance of a circuit is the inverse  of the time needed to perform a 32-bit operation.


Exercise 4.6 Problems in this exercise assume that logic blocks needed to implement a processor’s datapath have the following latencies:


4.6.1 [10] <4.3> If the only thing we need to do in a processor is fetch consecutive instructions (Figure 4.6),
what would the cycle time be?


4.6.2 [10] <4.3> Consider a datapath similar to the one in Figure 4.11, but for a  processor that only has one type of instruction: unconditional PC-relative branch.  What would the cycle time be for this datapath?
4.6.3 [10] <4.3> Repeat 4.6.2, but this time we need to support only conditional  PC-relative branches.
The remaining three problems in this exercise refer to the following logic block  (resource) in the datapath:


4.6.4 [10] <4.3> Which kinds of instructions require this resource?
4.6.5 [20] <4.3> For which kinds of instructions (if any) is this resource on the  critical path?
4.6.6[10] <4.3> Assuming that we only support BEQ and ADD instructions, discuss how changes in the 
given latency of this resource affect the cycle time of the processor. 
Assume that the latencies of other resources do not change.


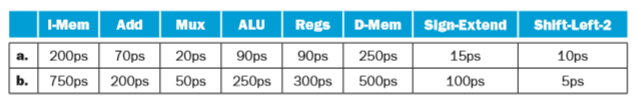
Exercise 4.7 In this exercise we examine how latencies of individual components of the datapath affect the clock cycle time of the entire datapath, and how these components  are utilized by instructions. For problems in this exercise, assume the following  latencies for logic blocks in the datapath:


4.7.1 [10] <4.3> What is the clock cycle time if the only types of instructions we  need to support are ALU instructions (ADD, AND, etc.)?
4.7.2 [10] <4.3> What is the clock cycle time if we only have to support LW  instructions?
4.7.3 [20] <4.3> What is the clock cycle time if we must support ADD, BEQ, LW,  and SW instructions?
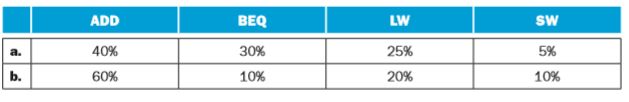
For the remaining problems in this exercise, assume that there are no pipeline stalls  and that the breakdown of executed instructions is as follows:


4.7.4 [10] <4.3> In what fraction of all cycles is the data memory used?
4.7.5 [10] <4.3> In what fraction of all cycles is the input of the sign-extend  circuit needed? What is this circuit doing in cycles in which its input is not  needed?
4.7.6 [10] <4.3> If we can improve the latency of one of the given datapath components by 10%, which component should it be? What is the speedup from this  improvement?
Exercise 4.8 

When silicon chips are fabricated, defects in materials (e.g., silicon) and manufacturing errors can result in defective circuits. A very common defect is for one wire  to affect the signal in another. This is called a cross-talk fault. A special class of cross-talk faults is when a signal is connected to a wire that has a constant logical  value (e.g., a power supply wire). In this case we have a stuck-at-0 or a stuck-at-1  fault, and the affected signal always has a logical value of 0 or 1, respectively.
The following problems refer to the following signal from Figure 4.24:
Signal
a. Registers, input Write Register, bit 0 

b. Add unit in upper right corner, ALU result, bit 0


4.8.1 [10] <4.3, 4.4> Let us assume that processor testing is done by filling the  PC, registers, and data and instruction memories with some values (you can choose  which values), letting a single instruction execute, then reading the PC, memories,  and registers. These values are then examined to determine if a particular fault is  present. Can you design a test (values for PC, memories, and registers) that would  determine if there is a stuck-at-0 fault on this signal?


4.8.2 [10] <4.3, 4.4> Repeat 4.8.1 for a stuck-at-1 fault. Can you use a single test for both stuck-at-0 and stuck-at-1? If yes, explain how; if no, explain  why not.


4.8.3 [60] <4.3, 4.4> If we know that the processor has a stuck-at-1 fault on this  signal, is the processor still usable? To be usable, we must be able to convert any  program that executes on a normal MIPS processor into a program that works on  this processor. You can assume that there is enough free instruction memory and  data memory to let you make the program longer and store additional data. Hint:  the processor is usable if every instruction “broken” by this fault can be replaced  with a sequence of “working” instructions that achieve the same effect.
The following problems refer to the following fault:
Fault
a. Stuck-at-0 

b. Becomes 0 if RegDst control signal is 0, no fault otherwise


4.8.4 [10] <4.3, 4.4> Repeat 4.8.1, but now the fault to test for is whether the  “MemRead” control signal has this fault.


4.8.5 [10] <4.3, 4.4> Repeat 4.8.1, but now the fault to test for is whether the  “Jump” control signal has this fault.


4.8.6 [40] <4.3, 4.4> Using a single test described in 4.8.1, we can test for faults  in several different signals, but typically not all of them. Describe a series of tests  to look for this fault in all Mux outputs (every output bit from each of the five  Muxes). Try to do this with as few single-instruction tests as possible.


Exercise 4.9 

In this exercise we examine the operation of the single-cycle datapath for a particular instruction. Problems in this exercise refer to the following MIPS instruction:
Instruction
a. SW R4,–100(R16) 

b. SLT R1,R2,R3


4.9.1 [10] <4.4> What is the value of the instruction word?


4.9.2 [10] <4.4> What is the register number supplied to the register file’s “Read  register 1” input? Is this register actually read? How about “Read register 2”?


4.9.3 [10] <4.4> What is the register number supplied to the register file’s “Write  register” input? Is this register actually written?

Different instructions require different control signals to be asserted in the datapath. The remaining problems in this exercise refer to the following two control  signals from Figure 4.24:


4.9.4 [20] <4.4> What is the value of these two signals for this instruction?


4.9.5 [20] <4.4> For the datapath from Figure 4.24, draw the logic diagram for  the part of the control unit that implements just the first signal. Assume that we  only need to support LW, SW, BEQ, ADD, and J (jump) instructions.


4.9.6 [20] <4.4> Repeat 4.9.5, but now implement both of these signals.


Exercise
4.10 In this exercise we examine how the clock cycle time of the processor affects the  design of the control unit, and vice versa. Problems in this exercise assume that the  logic blocks used to implement the datapath have the following latencies:
 

4.10.1 [10] <4.2, 4.4> To avoid lengthening the critical path of the datapath  shown in Figure 4.24, how much time can the control unit take to generate the  MemWrite signal?
4.10.2 [20] <4.2, 4.4> Which control signal in Figure 4.24 has the most slack and  how much time does the control unit have to generate it if it wants to avoid being  on the critical path?
4.10.3 [20] <4.2, 4.4> Which control signal in Figure 4.24 is the most critical to  generate quickly and how much time does the control unit have to generate it if it  wants to avoid being on the critical path?
The remaining problems in this exercise assume that the time needed by the control unit to generate individual control signals is as follows


4.10.4 [20] <4.4> What is the clock cycle time of the processor?
4.10.5 [20] <4.4> If you can speed up the generation of control signals, but the  cost of the entire processor increases by $1 for each 5ps improvement of a single control signal, which control signals would you speed up and by how much  to maximize performance? What is the cost (per processor) of this performance  improvement?
4.10.6 [30] <4.4> If the processor is already too expensive, instead of paying to  speed it up as we did in 4.10.5, we want to minimize its cost without further slowing it down. If you can use slower logic to implement control signals, saving $1 of  the processor cost for each 5ps you add to the latency of a single control signal,  which control signals would you slow down and by how much to reduce the processor’s cost without 
slowing it down?


Exercise 4.11 
In this exercise we examine in detail how an instruction is executed in a single-cycle  datapath. Problems in this exercise refer to a clock cycle in which the processor  fetches the following instruction word:
Instruction word
a. 10101100011000100000000000010100 

b. 00000000100000100000100000101010


4.11.1 [5] <4.4> What are the outputs of the sign-extend and the jump “Shift left  2” unit (near the top of Figure 4.24) for this instruction word?


4.11.2 [10] <4.4> What are the values of the ALU control unit’s inputs for this  instruction?


4.11.3 [10] <4.4> What is the new PC address after this instruction is executed?  Highlight the path through which this value is determined.
The remaining problems in this exercise assume that data memory is all zeros and  that the processor’s registers have the following values at the beginning of the cycle  in which the above instruction word is fetched:


4.11.4 [10] <4.4> For each Mux, show the values of its data output during the  execution of this instruction and these register values.
4.11.5 [10] <4.4> For the ALU and the two add units, what are their data input values?
4.11.6 [10] <4.4> What are the values of all inputs for the “Registers” unit?


Exercise 4.12 

In this exercise, we examine how pipelining affects the clock cycle time of the processor. Problems in this exercise assume that individual stages of the datapath have  the following latencies:


4.12.1 [5] <4.5> What is the clock cycle time in a pipelined and non-pipelined  processor?
Get 4.12.1 exercise solution
4.12.2 [10] <4.5> What is the total latency of an LW instruction in a pipelined  and non-pipelined processor?
4.12.3 [10] <4.5> If we can split one stage of the pipelined datapath into two new  stages, each with half the latency of the original stage, which stage would you split  and what is the new clock cycle time of the processor?
The remaining problems in this exercise assume that instructions executed by the  processor are broken down as follows:


Get 4.12.3 exercise solution
4.12.4 [10] <4.5> Assuming there are no stalls or hazards, what is the utilization   of the data memory?
4.12.5 [10] <4.5> Assuming there are no stalls or hazards, what is the utilization  of the write-register port of the “Registers” unit?
4.12.6 [30] <4.5> Instead of a single-cycle organization, we can use a multicycle organization where each instruction takes multiple cycles but one instruction  finishes before another is fetched. In this organization, an instruction only goes  through stages it actually needs (e.g., ST only takes 4 cycles because it does not need  the WB stage). Compare clock cycle times and execution times with single-cycle,  multi-cycle, and pipelined organization.


Exercise 4.13
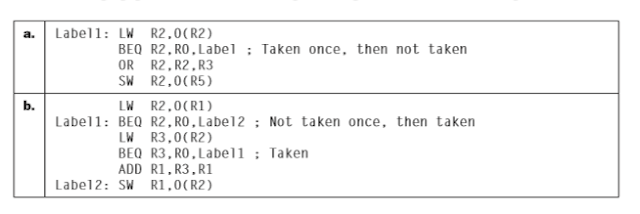
In this exercise, we examine how data dependences affect execution in the basic  5-stage pipeline described in Section 4.5. Problems in this exercise refer to the following sequence of instructions:
Instruction Sequence
a. 

SW R16,–100(R6) 
LW R4,8(R16) 
ADD R5,R4,R4 
b. 
OR R1,R2,R3 
OR R2,R1,R4 
OR R1,R1,R2

4.13.1 [10] <4.5> Indicate dependences and their type.
4.13.2 [10] <4.5> Assume there is no forwarding in this pipelined processor.  Indicate hazards and add NOP instructions to eliminate them.
4.13.3 [10] <4.5> Assume there is full forwarding. Indicate hazards and add NOP  instructions to eliminate them.


4.13.4 [10] <4.5> What is the total execution time of this instruction sequence  without forwarding and with full forwarding? What is the speedup achieved by  adding full forwarding to a pipeline that had no forwarding?
4.13.5 [10] <4.5> Add NOP instructions to this code to eliminate hazards if there  is ALU-ALU forwarding only (no forwarding from the MEM to the EX stage).
4.13.6 [10] <4.5> What is the total execution time of this instruction sequence  with only ALU-ALU forwarding? What is the speedup over a no-forwarding pipeline?


Exercise 4.14 
In this exercise, we examine how resource hazards, control hazards, and ISA design  can affect pipelined execution. Problems in this exercise refer to the following fragment of MIPS code:


4.14.1 [10] <4.5> For this problem, assume that all branches are perfectly predicted (this eliminates all control 
hazards) and that no delay slots are used. If we only have one memory (for both instructions and data), there is a structural hazard every time we need to fetch an instruction in the same cycle in which another  instruction accesses data. To guarantee forward progress, this hazard must always  be resolved in favor of the instruction that accesses data. What is the total execution  time of this instruction sequence in the 5-stage pipeline that only has one memory?  We have seen that data hazards can be eliminated by adding NOPs to the code. Can  you do the same with this structural hazard? Why?
4.14.2 [20] <4.5> For this problem, assume that all branches are perfectly predicted (this eliminates all control hazards) and that no delay slots are used. If we  change load/store instructions to use a register (without an offset) as the address,  these instructions no longer need to use the ALU. As a result, MEM and EX stages  can be overlapped and the pipeline has only 4 stages. Change this code to accommodate this changed ISA. Assuming this change does not affect clock cycle time,  what speedup is achieved in this instruction sequence?
4.14.3 [10] <4.5> Assuming stall-on-branch and no delay slots, what speedup is  achieved on this code if branch outcomes are determined in the ID stage, relative to  the execution where branch outcomes are determined in the EX stage?
The remaining problems in this exercise assume that individual pipeline stages  have the following latencies:


4.14.4 [10] <4.5> Given these pipeline stage latencies, repeat the speedup calculation from 4.14.2, but take into account the (possible) change in clock cycle  time. When EX and MEM are done in a single stage, most of their work can be  done in parallel. As a result, the resulting EX/MEM stage has a latency that is the  larger of the original two, plus 20ps needed for the work that could not be done  in parallel.
4.14.5 [10] <4.5> Given these pipeline stage latencies, repeat the speedup  calculation from 4.14.3, taking into account the (possible) change in clock  cycle time. Assume that the latency ID stage increases by 50% and the latency  of the EX stage decreases by 10ps when branch outcome resolution is moved  from EX to ID.
4.14.6 [10] <4.5> Assuming stall-on-branch and no delay slots, what is the new  clock cycle time and execution time of this instruction sequence if BEQ address computation is moved to the MEM stage? What is the speedup from this change?  Assume that the latency of the EX stage is reduced by 20ps and the latency of  the MEM stage is unchanged when branch outcome resolution is moved from EX  to MEM.


Exercise 4.15 
In this exercise, we examine how the ISA affects pipeline design. Problems in this  exercise refer to the following new instruction:

4.15.1 [20] <4.5> What must be changed in the pipelined datapath to add this  instruction to the MIPS ISA?
4.15.2 [10] <4.5> Which new control signals must be added to your pipeline  from 4.15.1?
4.15.3 [20] <4.5, 4.13> Does support for this instruction introduce any new hazards? 
Are stalls due to existing hazards made worse?

4.15.4 [10] <4.5, 4.13> Give an example of where this instruction might be useful  and a sequence of existing MIPS instructions that are replaced by this instruction.


4.15.5 [10] <4.5, 4.11, 4.13> If this instruction already exists in a legacy ISA,  explain how it would be executed in a modern processor like AMD Barcelona.
The last problem in this exercise assumes that each use of the new instruction  replaces the given number of original instructions, that the replacement can be  made once in the given number of original instructions, and that each time the  new instruction is executed the given number of extra stall cycles is added to the  program’s execution time:


4.15.6 [10] <4.5> What is the speedup achieved by adding this new instruction?  In your calculation, assume that the CPI of the original program (without the new  instruction) is 1.


Exercise 4.16 
The first three problems in this exercise refer to the following MIPS instruction:
Instruction
a. SW R16,–100(R6) 

b. OR R2,R1,R0


4.16.1 [5] <4.6> As this instruction executes, what is kept in each register located  between two pipeline stages?


4.16.2 [5] <4.6> Which registers need to be read, and which registers are actually  read?


4.16.3 [5] <4.6> What does this instruction do in the EX and MEM stages?
The remaining three problems in this exercise refer to the following loop. Assume  that perfect branch prediction is used (no stalls due to control hazards), that there  are no delay slots, and that the pipeline has full forwarding support. Also assume  that many iterations of this loop are executed before the loop exits.


4.16.4 [10] <4.6> Show a pipeline execution diagram for the third iteration of  this loop, from the cycle in which we fetch the first instruction of that iteration up  to (but not including) the cycle in which we can fetch the first instruction of the  next iteration. Show all instructions that are in the pipeline during these cycles (not  just those from the third iteration).
4.16.5 [10] <4.6> How often (as a percentage of all cycles) do we have a cycle in  which all five pipeline stages are doing useful work?
4.16.6 [10] <4.6> At the start of the cycle in which we fetch the first instruction  of the third iteration of this loop, what is stored in the IF/ID register?


Exercise 4.17 Problems in this exercise assume that instructions executed by a pipelined processor are broken down as follows:


4.17.1 [5] <4.6> Assuming there are no stalls and that 60% of all conditional  branches are taken, in what percentage of clock cycles does the branch adder in the  EX stage generate a value that is actually used?
4.17.2 [5] <4.6> Assuming there are no stalls, how often (percentage of all cycles)  do we actually need to use all three register ports (two reads and a write) in the  same cycle?
Get 4.17.2 exercise solution
4.17.3 [5] <4.6> Assuming there are no stalls, how often (percentage of all cycles)  do we use the data memory?
Each pipeline stage in Figure 4.33 has some latency. Additionally, pipelining  introduces registers between stages (Figure 4.35), and each of these adds an additional latency. The remaining problems in this exercise assume the following  latencies for logic within each pipeline stage and for each register between two  stages:


4.17.4 [5] <4.6> Assuming there are no stalls, what is the speedup achieved by  pipelining a single-cycle datapath?
4.17.5 [10] <4.6> We can convert all load/store instructions into register-based  (no offset) and put the memory access in parallel with the ALU. What is the clock  cycle time if this is done in the single-cycle and in the pipelined datapath? Assume  that the latency of the new EX/MEM stage is equal to the longer of their latencies.
4.17.6 [10] <4.6> The change in 4.17.5 requires many existing LW/SW instructions to be converted into two-instruction sequences. If this is needed for 50%  of these instructions, what is the overall speedup achieved by changing from the  5-stage pipeline to the 4-stage pipeline where EX and MEM are done in parallel?


Exercise 4.18 
The first three problems in this exercise refer to the execution of the following  instruction in the pipelined datapath from Figure 4.51, and assume the following  clock cycle time, ALU latency, and Mux latency:


4.18.1 [10] <4.6> For each stage of the pipeline, what are the values of the control  signals asserted by this instruction in that pipeline stage?

4.18.2 [10] <4.6, 4.7> How much time does the control unit have to generate the  ALUSrc control signal? Compare this to a single-cycle organization.
4.18.3  What is the value of the PCSrc signal for this instruction? This signal is  generated early in the MEM stage (only a single AND gate). What would be a reason in favor of doing this in the EX stage? What is the reason against doing it in the  EX stage? The remaining problems in this exercise refer to the following signals from    Figure 4.48:


4.18.4 [5] <4.6> For each of these signals, identify the pipeline stage in which it  is generated and the stage in which it is used.
4.18.5 [5] <4.6> For which MIPS instruction(s) are both of these signals set to 1?
4.18.6 [10] <4.6> One of these signals goes back through the pipeline. Which  signal is it? Is this a time-travel paradox? Explain.


Exercise 4.19 

This exercise is intended to help you understand the cost/complexity/performance  trade-offs of forwarding in a pipelined processor. Problems in this exercise refer  to pipelined datapaths from Figure 4.45. These problems assume that, of all the  instructions executed in a processor, the following fraction of these instructions have a particular type of RAW data dependence. The type of RAW data dependence  is identified by the stage that produces the result (EX or MEM) and the instruction  that consumes the result (1st instruction that follows the one that produces the  result, 2nd instruction that follows, or both). We assume that the register write is  done in the first half of the clock cycle and that register reads are done in the second  half of the cycle, so “EX to 3rd” and “MEM to 3rd” dependences are not counted  because they cannot result in data hazards. Also, assume that the CPI of the processor is 1 if there are no data hazards.


4.19.1 [10] <4.7> If we use no forwarding, what fraction of cycles are we stalling  due to data hazards?
4.19.2 [5] <4.7> If we use full forwarding (forward all results that can be forwarded), what fraction of cycles
 are we staling due to data hazards?
4.19.3 [10] <4.7> Let us assume that we cannot afford to have three-input Muxes  that are needed for full forwarding. We have to decide if it is better to forward  only from the EX/MEM pipeline register (next-cycle forwarding) or only from  the MEM/WB pipeline register (two-cycle forwarding). Which of the two options  results in fewer data stall cycles?
The remaining three problems in this exercise refer to the following latencies for  individual pipeline stages. For the EX stage, latencies are given separately for a processor without forwarding and for a processor with different kinds of forwarding.


4.19.4 [10] <4.7> For the given hazard probabilities and pipeline stage latencies,  what is the speedup achieved by adding full forwarding to a pipeline that had no  forwarding?
4.19.5 [10] <4.7> What would be the additional speedup (relative to a processor with forwarding) if we added time-travel forwarding that eliminates all data   hazards? Assume that the yet-to-be-invented time-travel circuitry adds 100ps to  the latency of the full-forwarding EX stage.
4.19.6 [20] <4.7> Repeat 4.19.3 but this time determine which of the two options  results in shorter time per instruction.


Exercise 4.20 
Problems in this exercise refer to the following instruction sequences:

4.20.1 [5] <4.7> Find all data dependences in this instruction sequence.
4.20.2 [10] <4.7> Find all hazards in this instruction sequence for a 5-stage pipeline with and then without forwarding.
4.20.3 [10] <4.7> To reduce clock cycle time, we are considering a split of the  MEM stage into two stages. Repeat 4.20.2 for this 6-stage pipeline.
The remaining three problems in this exercise assume that, before any of the above  is executed, all values in data memory are zeroes and that registers R0 through R3  have the following initial values:


4.20.4 [5] <4.7> Which value is the first one to be forwarded and what is the  value it overrides?
4.20.5 [10] <4.7> If we assume forwarding will be implemented when we design  the hazard detection unit, but then we forget to actually implement forwarding,  what are the final register values after this instruction sequence?

4.20.6 [10] <4.7> For the design described in 4.20.5, add NOPs to this instruction  sequence to ensure correct execution in spite of missing support for forwarding.

Exercise 4.21 

This exercise is intended to help you understand the relationship between forwarding, hazard detection, and ISA design. Problems in this exercise refer to the following sequences of instructions, and assume that it is executed on a 5-stage pipelined  datapath:


4.21.1 [5] <4.7> If there is no forwarding or hazard detection, insert NOPs to  ensure correct execution.
4.21.2 [10] <4.7> Repeat 4.21.1 but now use NOPs only when a hazard cannot be  avoided by changing or rearranging these instructions. You can assume register R7  can be used to hold temporary values in your modified code.
4.21.3 [10] <4.7> If the processor has forwarding, but we forgot to implement  the hazard detection unit, what happens when this code executes?
4.21.4 [20] <4.7> If there is forwarding, for the first five cycles during the execution of this code, specify 
which signals are asserted in each cycle by hazard detection and forwarding units in Figure 4.60.
4.21.5 [10] <4.7> If there is no forwarding, what new inputs and output signals  do we need for the hazard detection unit in Figure 4.60? Using this instruction  sequence as an example, explain why each signal is needed.
4.21.6 [20] <4.7> For the new hazard detection unit from 4.21.5, specify which  output signals it asserts in each of the first five cycles during the execution of this  code.


Exercise 4.22 

This exercise is intended to help you understand the relationship between delay  slots, control hazards, and branch execution in a pipelined processor. In this exercise, we assume that the following MIPS code is executed on a pipelined processor  with a 5-stage pipeline, full forwarding, and a predict-taken branch predictor: 


4.22.1 [10] <4.8> Draw the pipeline execution diagram for this code, assuming  there are no delay slots and that branches execute in the EX stage.


4.22.2 [10] <4.8> Repeat 4.22.1, but assume that delay slots are used. In the given  code, the instruction that follows the branch is now the delay slot instruction for  that branch.


4.22.3 [20] <4.8> One way to move the branch resolution one stage earlier is  to not need an ALU operation in conditional branches. The branch instructions  would be “BEZ Rd,Label” and “BNEZ Rd,Label”, and it would branch if the register has and does not have a zero value, respectively. Change this code to use these  branch instructions instead of BEQ. You can assume that register R8 is available for  you to use as a temporary register, and that an SEQ (set if equal) R-type instruction  can be used.
Section 4.8 describes how the severity of control hazards can be reduced by moving  branch execution into the ID stage. This approach involves a dedicated comparator  in the ID stage, as shown in Figure 4.62. However, this approach potentially adds  to the latency of the ID stage, and requires additional forwarding logic and hazard  detection.


4.22.4 [10] <4.8> Using the first branch instruction in the given code as an  example, describe the hazard detection logic needed to support branch execution  in the ID stage as in Figure 4.62. Which type of hazard is this new logic supposed  to detect?

4.22.5 [10] <4.8> For the given code, what is the speedup achieved by moving  branch execution into the ID stage? Explain your answer. In your speedup calculation, assume that the additional comparison in the ID stage does not affect clock  cycle time.


4.22.6 [10] <4.8> Using the first branch instruction in the given code as an  example, describe the forwarding support that must be added to support branch  execution in the ID stage. Compare the complexity of this new forwarding unit to  the complexity of the existing forwarding unit in Figure 4.62.


Exercise 4.23 The importance of having a good branch predictor depends on how often conditional branches are executed. Together with branch predictor accuracy, this will  determine how much time is spent stalling due to mispredicted branches. In this  exercise, assume that the breakdown of dynamic instructions into various instruction categories is as follows:


4.23.1 [10] <4.8> Stall cycles due to mispredicted branches increase the CPI.  What is the extra CPI due to mispredicted branches with the always-taken predictor? Assume that branch outcomes are determined in the EX stage, that there are  no data hazards, and that no delay slots are used.


4.23.2 [10] <4.8> Repeat 4.23.1 for the “always-not-taken” predictor.


4.23.3 [10] <4.8> Repeat 4.23.1 for the 2-bit predictor.


4.23.4 [10] <4.8> With the 2-bit predictor, what speedup would be achieved if  we could convert half of the branch instructions in a way that replaces a branch  instruction with an ALU instruction? Assume that correctly and incorrectly predicted instructions have  the same chance of being replaced.


4.23.5 [10] <4.8> With the 2-bit predictor, what speedup would be achieved if  we could convert half of the branch instructions in a way that replaced each branch  instruction with two ALU instructions? Assume that correctly and incorrectly predicted  instructions have the same chance of being replaced.


4.23.6 [10] <4.8> Some branch instructions are much more predictable than  others. If we know that 80% of all executed branch instructions are easy-to-predict  loop-back branches that are always predicted correctly, what is the accuracy of the  2-bit predictor on the remaining 20% of the branch instructions?


Exercise 4.24
This exercise examines the accuracy of various branch predictors for the following  repeating pattern (e.g., in a loop) of branch outcomes:


4.24.1 [5] <4.8> What is the accuracy of always-taken and always-not-taken predictors for this sequence of branch outcomes?


4.24.2 [5] <4.8> What is the accuracy of the two-bit predictor for the first 4  branches in this pattern, assuming that the predictor starts off in the bottom left  state from Figure 4.63 (predict not taken)?


4.24.3 [10] <4.8> What is the accuracy of the two-bit predictor if this pattern is  repeated forever?


4.24.4 [30] <4.8> Design a predictor that would achieve a perfect accuracy if  this pattern is repeated forever. You predictor should be a sequential circuit with  one output that provides a prediction (1 for taken, 0 for not taken) and no inputs  other than the clock and the control signal that indicates that the instruction is a  conditional branch.


 4.24.5 [10] <4.8> What is the accuracy of your predictor from 4.24.4 if it is given  a repeating pattern that is the exact opposite of this one?
Get 4.24.5 exercise solution


4.24.6 [20] <4.8> Repeat 4.24.4, but now your predictor should be able to eventually (after a warm-up period during which it can make wrong predictions) start  perfectly predicting both this pattern and its opposite. Your predictor should have  an input that tells it what the real outcome was. Hint: this input lets your predictor  determine which of the two repeating patterns it is given.


Exercise 4.25 
This exercise explores how exception handling affects pipeline design. The first  three problems in this exercise refer to the following two instructions:


4.25.1 [5] <4.9> Which exceptions can each of these instructions trigger? For  each of these exceptions, specify the pipeline stage in which it is detected.


4.25.2 [10] <4.9> If there is a separate handler address for each exception, show  how the pipeline organization must be changed to be able to handle this exception.  You can assume that the addresses of these handlers are known when the processor  is designed.


4.25.3 [10] <4.9> If the second instruction from this table is fetched right after  the instruction from the first table, describe what happens in the pipeline when the  first instruction causes the first exception you listed in 4.25.1. Show the pipeline  execution diagram from the time the first instruction is fetched until the time the  first instruction of the exception handler is completed.
The remaining three problems in this exercise assume that exception handlers are  located at the following addresses: 


4.25.4 [5] <4.9> What is the address of the exception handler in 4.25.3?  What happens if there is an invalid instruction at that address in instruction  memory?


4.25.5 [20] <4.9> In vectored exception handling, the table of exception handler  addresses is in data memory at a known (fixed) address. Change the pipeline to  implement this exception handling mechanism. Repeat 4.25.3 using this modified  pipeline and vectored exception handling.


4.25.6 [15] <4.9> We want to emulate vectored exception handling (described in  4.25.5) on a machine that has only one fixed handler address. Write the code that  should be at that fixed address. Hint: this code should identify the exception, get  the right address from the exception vector table, and transfer execution to that  handler.


Exercise 4.26 This exercise explores how exception handling affects control unit design and processor clock cycle time. The first three problems in this exercise refer to the following MIPS instruction that triggers an exception:


4.26.1 [10] <4.9> For each stage of the pipeline, determine the values of exception-related control signals from Figure 4.66 as this instruction passes through that  pipeline stage.


4.26.2 [5] <4.9> Some of the control signals generated in the ID stage are stored  into the ID/EX pipeline register, and some go directly into the EX stage. Explain  why, using this instruction as an example.


4.26.3 [10] <4.9> We can make the EX stage faster if we check for exceptions  in the stage after the one in which the exceptional condition occurs. Using this  instruction as an example, describe the main disadvantage of this approach.
The remaining three problems in this exercise assume that pipeline stages have the  following latencies:


4.26.4 [10] <4.9> If an overflow exception occurs once for every 100,000 instructions executed, what is the overall speedup if we move overflow checking into the  MEM stage? Assume that this change reduces EX latency by 30ns and that the IPC  achieved by the pipelined processor is 1 when there are no exceptions.


4.26.5 [20]  <4.9>  Can  we  generate  exception  control  signals  in  EX  instead  of in ID? Explain how this will work or why it will not work, using the “BNE R4,R5,Label” instruction and these pipeline stage latencies as an example.


4.26.6 [10] <4.9> Assuming that each Mux has a latency of 40ps, determine how  much time does the control unit have to generate the flush signals? Which signal is  the most critical?


Exercise 4.27 
This exercise examines how exception handling interacts with branch and load/ store instructions. Problems in this exercise refer to the following branch instruction and the corresponding delay slot instruction:


4.27.1 [20] <4.9> Assume that this branch is correctly predicted as taken, but  then the instruction at “Label” is an undefined instruction. Describe what is done  in each pipeline stage for each cycle, starting with the cycle in which the branch is  decoded up to the cycle in which the first instruction of the exception handler is  fetched.


4.27.2 [10] <4.9> Repeat 4.27.1, but this time assume that the instruction in the  delay slot also causes a hardware error exception when it is in MEM stage.


4.27.3 [10] <4.9> What is the value in the EPC if the branch is taken but the  delay slot causes an exception? What happens after the execution of the exception  handler is completed?
The remaining three problems in this exercise also refer to the following store  instruction:


4.27.4 [10] <4.9> What happens if the branch is taken, the instruction at “Label”  is an invalid instruction, the first instruction of the exception handler is the SW  instruction given above, and this store accesses an invalid data address?
Get 4.27.4 exercise solution


4.27.5 [10] <4.9> If LD/ST address computation can overflow, can we delay  overflow exception detection into the MEM stage? Use the given store instruction  to explain what happens.


4.27.6 [10] <4.9> For debugging, it is useful to be able to detect when a particular value is written to a particular memory address. We want to add two new  registers, WADDR and WVAL. The processor should trigger an exception when the value equal to WVAL is about to be written to address WADDR. How would you  change the pipeline to implement this? How would this SW instruction be handled  by your modified datapath?


Exercise 4.28 
In this exercise we compare the performance of 1-issue and 2-issue processors, taking into account program transformations that can be made to optimize for 2-issue  execution. Problems in this exercise refer to the following loop (written in C):


 When writing MIPS code, assume that variables are kept in registers as follows, and  that all registers except those indicated as Free are used to keep various variables,  so they cannot be used for anything else.


4.28.1 [10] <4.10> Translate this C code into MIPS instructions. Your translation  should  be  direct,  without  rearranging  instructions  to  achieve  better  performance.


4.28.2 [10] <4.10> If the loop exits after executing only two iterations, draw a  pipeline diagram for your MIPS code from 4.28.1 executed on a 2-issue processor  shown in Figure 4.69. Assume the processor has perfect branch prediction and can  fetch any two instructions (not just consecutive instructions) in the same cycle.


4.28.3 [10] <4.10> Rearrange your code from 4.28.1 to achieve better performance on a 2-issue statically scheduled processor from Figure 4.69.


4.28.4 [10] <4.10> Repeat 4.28.2, but this time use your MIPS code from 4.28.3.


4.28.5 [10] <4.10> What is the speedup of going from a 1-issue processor to a  2-issue processor from Figure 4.69? Use your code from 4.28.1 for both 1-issue  and 2-issue, and assume that 1,000,000 iterations of the loop are executed. As in 4.28.2, assume that the processor has perfect branch predictions, and that a 2-issue  processor can fetch any two instructions in the same cycle.


4.28.6 [10] <4.10> Repeat 4.28.5, but this time assume that in the 2-issue processor one of the instructions to be executed in a cycle can be of any kind, and the  other must be a non-memory instruction.


Exercise 4.29 In this exercise, we consider the execution of a loop in a statically scheduled superscalar processor. To simplify the exercise, assume that any combination of instruction types can execute in the same cycle, e.g., in a 3-issue superscalar, the three  instructions can be 3 ALU operations, 3 branches, 3 load/store instructions, or any  combination of these instructions. Note that this only removes a resource constraint, but data and control dependences must still be handled correctly. Problems  in this exercise refer to the following loop:


4.29.1 [10] <4.10> If many (e.g., 1,000,000) iterations of this loop are executed,  determine the fraction of all register reads that are useful in a 2-issue static superscalar processor.


4.29.2 [10] <4.10> If many (e.g., 1,000,000) iterations of this loop are executed, determine the fraction of all register reads that are useful in a 3-issue  static superscalar processor. Compare this to your result for a 2-issue processor  from 4.29.1.


4.29.3 [10] <4.10> If many (e.g., 1,000,000) iterations of this loop are executed,  determine the fraction of cycles in which two or three register write ports are used  in a 3-issue static superscalar processor. 


4.29.4 [20] <4.10> Unroll this loop once and schedule it for a 2-issue static  superscalar processor. Assume that the loop always executes an even number of iterations. You can use registers R10 through R20 when changing the code to eliminate dependences.


4.29.5 [20] <4.10> What is the speedup of using your code from 4.29.4 instead  of the original code with a 2-issue static superscalar processor? Assume that the  loop has many (e.g., 1,000,000) iterations.


4.29.6 [10] <4.10> What is the speedup of using your code from 4.29.4 instead  of the original code with a pipelined (1-issue) processor? Assume that the loop has  many (e.g., 1,000,000) iterations.


Exercise 4.30
In this exercise, we make several assumptions. First, we assume that an N-issue  superscalar processor can execute any N instructions in the same cycle, regardless  of their types. Second, we assume that every instruction is independently chosen,  without regard for the instruction that precedes or follows it. Third, we assume that  there are no stalls due to data dependences, that no delay slots are used, and that  branches execute in the EX stage of the pipeline. Finally, we assume that instructions executed in the program are distributed as follows:


4.30.1 [5] <4.10> What is the CPI achieved by a 2-issue static superscalar processor on this program?

4.30.2 [10] <4.10> In a 2-issue static superscalar whose predictor can only handle one branch per cycle, what speedup is achieved by adding the ability to predict  two branches per cycle? Assume a stall-on-branch policy for branches that the predictor cannot handle. 


4.30.3 [10] <4.10> In a 2-issue static superscalar processor that only has one register write port, what speedup is achieved by  adding a second register write port?


4.30.4 [5] <4.10> For a 2-issue static superscalar processor with a classic 5-stage  pipeline, what speedup is achieved by making the branch prediction perfect? 


4.30.5 [10] <4.10> Repeat 4.30.4, but for a 4-issue processor. What conclusion  can you draw about the importance of good branch prediction when the issue  width of the processor is increased?


4.30.6 <4.10> Repeat 4.30.5, but now assume that the 4-issue processor has 50  pipeline stages. Assume that each of the original 5 stages is broken into 10 new  stages, and that branches are executed in the first of ten new EX stages. What conclusion can you draw about the importance of good branch prediction when  the pipeline depth of the processor is increased?


Exercise 4.31 
Problems in this exercise refer to the following loop, which is given as x86 code and also  as an MIPS translation of that code. You can assume that this loop executes many iterations before it exits. When determining performance, this means that you only need to  determine what the performance would be in the “steady state,” not for the first few and  the last few iterations of the loop. Also, you can assume full forwarding support and  perfect branch prediction without delay slots, so the only hazards you have to worry  about are resource hazards and data hazards. Note that most x86 instructions in this  problem have two operands each. The last (usually second) operand of the instruction  indicates both the first source data value and the destination. If the operation needs a  second source data value, it is indicated by the other operand of the instruction. For  example, “sub (edx),eax” reads the memory location pointed by register edx, subtracts  that value from register eax, and puts the result back in register eax.


4.31.1 [20] <4.11> What CPI would be achieved if the MIPS version of this loop  is executed on a 1-issue processor with static scheduling and a 5-stage pipeline? 


4.31.2 [20] <4.11> What CPI would be achieved if the X86 version of this loop  is executed on a 1-issue processor with static scheduling and a 7-stage pipeline?  The stages of the pipeline are IF, ID, ARD, MRD, EXE, and WB. Stages IF and ID  are similar to those in the 5-stage MIPS pipeline. ARD computes the address of  the memory location to be read, MRD performs the memory read, EXE executes the operation, and WB writes the result to register or memory. The data memory  has a read port (for instructions in the MRD stage) and a separate write port (for  instructions in the WB stage).


4.31.3 [20] <4.11> What CPI would be achieved if the X86 version of this loop is  executed on a processor that internally translates these instructions into MIPS-like  micro-operations, then executes these micro-operations on a 1-issue 5-stage pipeline with static scheduling. Note that the instruction count used in CPI computation for this  processor is the X86 instruction count.


4.31.4 [20] <4.11> What CPI would be achieved if the MIPS version of this loop  is executed on a 1-issue processor with dynamic scheduling? Assume that our processor is not doing register renaming, so you can only reorder instructions that  have no data dependences.


4.31.5 [30] <4.10, 4.11> Assuming that there are many free registers available,  rename the MIPS version of this loop to eliminate as many data dependences as  possible between instructions in the same iteration of the loop. Now repeat 4.31.4,  using your new renamed code.


4.31.6 [20] <4.10, 4.11> Repeat 4.31.4, but this time assume that the processor  assigns a new name to the result of each instruction as that instruction is decoded,  and then renames registers used by subsequent instructions to use correct register  values. 


Exercise 4.32 
Problems in this exercise assume that branches represent the following fraction  of all executed instructions, and the following branch predictor accuracy. Assume  that the processor is never stalled by data and resource dependences, i.e., the processor always fetches and executes the maximum number of instructions per cycle  if there are no control hazards. For control dependences, the processor uses branch  prediction and continues fetching from the predicted path. If the branch has been  mispredicted, when the branch outcome is resolved the instructions fetched after  the mispredicted branch are discarded, and in the next cycle the processor starts  fetching from the correct path.


4.32.1 [5] <4.11> How many instructions are expected to be executed between  the time one branch misprediction is detected and the time the next branch misprediction is detected?

The remaining problems in this exercise assume the following pipeline depth and  that the branch outcome is determined in the following pipeline stage (counting  from stage 1):


4.32.2 [5] <4.11> In a 4-issue processor with these pipeline parameters, how  many branch instructions can be expected to be “in progress” (already fetched but  not yet committed) at any given time?


4.32.3 [5] <4.11> How many instructions are fetched from the wrong path for  each branch misprediction in a 4-issue processor?


4.32.4 [10] <4.11> What is the speedup achieved by changing the processor from  4-issue to 8-issue? Assume that the 8-issue and the 4-issue processor differ only in  the number of instructions per cycle, and are otherwise identical (pipeline depth,  branch resolution stage, etc.).


4.32.5 [10] <4.11> What is the speedup of executing branches 1 stage earlier in  a 4-issue processor?


4.32.6 [10] <4.11> What is the speedup of executing branches 1 stage earlier in  an 8-issue processor? Discuss the difference between this result and the result from  4.32.5.


Exercise 4.33 This exercise explores how branch prediction affects performance of a deeply pipelined multiple-issue processor. Problems in this exercise refer to a processor with  the following number of pipeline stages and instructions issued per cycle:


4.33.1 [10] <4.11> How many register read ports should the processor have to  avoid any resource hazards due to register reads?


4.33.2 [10] <4.11> If there are no branch mispredictions and no data dependences, what is the expected performance improvement over a 1-issue processor  with the classical 5-stage pipeline? Assume that the clock cycle time decreases in  proportion to the number of pipeline stages

4.33.3 [10] <4.11> Repeat 4.33.2, but this time every executed instruction has  a RAW data dependence to the instruction that executes right after it. You can  assume that no stall cycles are needed, i.e., forwarding allows consecutive instructions to execute in back-to-back cycles.
For the remaining three problems in this exercise, unless the problem specifies otherwise, assume the following statistics about what percentage of instructions are  branches, predictor accuracy, and performance loss due to branch mispredictions: 


4.33.4 [10] <4.11> If we have the given fraction of branch instructions and  branch prediction accuracy, what percentage of all cycles are entirely spent fetching wrong-path instructions? Ignore the performance loss number.


 4.33.5 [20] <4.11> If we want to limit stalls due to mispredicted branches to no  more than the given percentage of the ideal (no stalls) execution time, what should  
 be our branch prediction accuracy? Ignore the given predictor accuracy number.


4.33.6 [10] <4.11> What should the branch prediction accuracy be if we are willing to have a speedup of  0.5 (one half) relative to the same processor with an ideal  branch predictor? 


Exercise 4.34 
This exercise is designed to help you understand the discussion of the “Pipelining is  easy” fallacy from Section 4.13. The first four problems in this exercise refer to the  following MIPS instruction:


4.34.1 [10] <4.13> Describe a pipelined datapath needed to support only this  instruction. Your datapath should be designed with the assumption that the only  instructions that will ever be executed are instances of this instruction.


4.34.2 [10] <4.13> Describe the requirements of forwarding and hazard detection units for your datapath  from 4.34.1.
 
 
4.34.3 [10] <4.13> What needs to be done to support undefined instruction  exceptions in your datapath from 4.34.1? Note that the undefined instruction  exception should be triggered whenever the processor encounters any other kind  of instruction. The remaining two problems in this exercise also refer to this MIPS instruction:


4.34.4 [10] <4.13> Describe how to extend your datapath from 4.34.1 so it can  also support this instruction. Your extended datapath should be designed to only  support instances of these two instructions.


4.34.5 [10] <4.13> Repeat 4.34.2 for your extended datapath from 4.34.4.


4.34.6 [10] <4.13> Repeat 4.34.3 for your extended datapath from 4.34.4.


Exercise 4.35
This exercise is intended to help you better understand the relationship between  ISA design and pipelining. Problems in this exercise assume that we have a multiple-issue  pipelined  processor  with  the  following  number  of  pipeline  stages,  instructions issued per cycle, stage in which branch outcomes are resolved, and  branch predictor accuracy:


 4.35.1 [5] <4.8, 4.13> Control hazards can be eliminated by adding branch delay  slots. How many delay slots must follow each branch if we want to eliminate all  control hazards in this processor?


4.35.2 [10] <4.8, 4.13> What is the speedup that would be achieved by using  four branch delay slots to reduce control hazards in this processor? Assume that  there are no data dependences between instructions and that all four delay slots  can be filled with useful instructions without increasing the number of executed  instructions. To make your computations easier, you can also assume that the mispredicted branch instruction is always the last instruction to be fetched in a cycle,  i.e., no instructions that are in the same pipeline stage as the branch are fetched  from the wrong path.
 

4.35.3 [10] <4.8, 4.13> Repeat 4.35.2, but now assume that 10% of executed  branches have all four delay slots filled with useful instruction, 20% have only three  useful instructions in delay slots (the fourth delay slot is an NOP), 30% have only  two useful instructions in delay slots, and 40% have no useful instructions in their  delay slots.
The remaining four problems in this exercise refer to the following C loop:


4.35.4 [10] <4.8, 4.13> Translate this C loop into MIPS instructions, assuming  that our ISA requires one delay slot for every branch. Try to fill delay slots with  non-NOP instructions when possible. You can assume that variables a, b, c, i,  and j are kept in registers r1, r2, r3, r4, and r5.


4.35.5 [10] <4.7, 4.13> Repeat 4.35.4 for a processor that has two delay slots for  every branch.


4.35.6 [10] <4.10, 4.13> How many iterations of your loop from 4.35.4 can be “in  flight” within this processor’s pipeline? We say that an iteration is “in flight” when  at least one of its instructions has been fetched and has not yet been committed.


Exercise 4.36 
This exercise is intended to help you better understand the last pitfall from Section  4.13—failure to consider pipelining in instruction set design. The first four problems in this exercise refer to the following new MIPS instruction:


4.36.1 [10] <4.11, 4.13> Translate this instruction into MIPS micro-operations.


4.36.2 [10] <4.11, 4.13> How would you change the 5-stage MIPS pipeline to  add support for micro-op translation needed to support this new instruction?
 

4.36.3 [20] <4.13> If we want to add this instruction to the MIPS ISA, discuss  the changes to the pipeline (which stages, which structures in which stage) that are  needed to directly (without micro-ops) support this instruction.


4.36.4 [10] <4.13> How often do you expect this instruction can be used? Do  you think that we would be justified if we added this instruction to the MIPS ISA?
The  remaining  two  problems  in  this  exercise  are  about  adding  a  new ADDM  instruction to the ISA. In a processor to which ADDM has been added, these problems assume the following breakdown of clock cycles according to which instruction is completed in that cycle (or which stall is preventing an instruction from  completing):


4.36.5 [10] <4.13> Given this breakdown of execution cycles in the processor with direct support for the ADDM instruction, what speedup is achieved by  replacing this instruction with a 3-instruction sequence (LW, ADD, and then SW)?  Assume that the ADDM instruction is somehow (magically) supported with a classical 5-stage pipeline without creating resource hazards.


4.36.6 [10] <4.13> Repeat 4.36.5, but now assume that ADDM was supported by  adding a pipeline stage. When ADDM is translated, this extra stage can be removed  and, as a result, half of the existing data stalls are eliminated. Note that the data stall  elimination applies only to stalls that existed before ADDM translation, not to stalls  added by the ADDM translation itself. 


Exercise 4.37 
This exercise explores some of the tradeoffs involved in pipelining, such as clock  cycle time and utilization of hardware resources. The first three problems in this  exercise refer to the following MIPS code. The code is written with an assumption  that the processor does not use delay slots.


4.37.1 [5] <4.3, 4.14> Which parts of the basic single-cycle datapath are used by  all of these instructions? Which parts are the least utilized?


4.37.2 [10] <4.6, 4.14> What is the utilization for the read and for the write port  of the data memory unit?


4.37.3 [10] <4.6, 4.14> Assume that we already have a single-cycle design. How  many bits in total do we need for pipeline registers to implement the pipelined  design?
The remaining three problems in this exercise assume that components of the datapath have the following latencies:


4.37.4 [10] <4.3, 4.5, 4.14> Given these latencies for individual elements of the  datapath, compare clock cycle times of the single-cycle and the 5-stage pipelined  datapath.


4.37.5 [10] <4.3, 4.5, 4.14> Repeat 4.37.4, but now assume that we only want to  support ADD instructions.


4.37.6 [20] <4.3, 4.5, 4.14> If it costs $1 to reduce the latency of a single component of the datapath by 1ps, what would it cost to reduce the clock cycle time by  20% in the single-cycle and in the pipelined design?


Exercise 4.38 
This exercise explores energy efficiency and its relationship with performance.  Problems in this exercise assume the following energy consumption for activity in  Instruction memory, Registers, and Data memory. You can assume that the other  components of the datapath spend a negligible amount of energy.


4.38.1 [10] <4.3, 4.6, 4.14> How much energy is spent to execute an ADD instruction in a single-cycle design and in the 5-stage pipelined design?
 

4.38.2 [10] <4.6, 4.14> What is the worst-case MIPS instruction in terms of  energy consumption, and what is the energy spent to execute it?


4.38.3 [10] <4.6, 4.14> If energy reduction is paramount, how would you change  the pipelined design? What is the percentage reduction in the energy spent by an  LW instruction after this change?
The remaining three problems in this exercise assume that components in the datapath have the following latencies. You can assume that the other components of the  datapath have negligible latencies.


4.38.4 [10] <4.6, 4.14> What is the performance impact of your changes from  4.38.3?


4.38.5 [10] <4.6, 4.14> We can eliminate the MemRead control signal and have  the data memory be read in every cycle, i.e., we can permanently have MemRead=1.  Explain why the processor still functions correctly after this change. What is the  effect of this change on clock frequency and energy consumption?


4.38.6 [10] <4.6, 4.14> If an idle unit spends 10% of the power it would spend  if it were active, what is the energy spent by the instruction memory in each cycle?  What percentage of the overall energy spent by the instruction memory does this  idle energy represent?


Exercise 4.39 Problems in this exercise assume that, during an execution of the program, processor cycles are spent in the following way. A cycle is “spent” on an instruction if the  processor completes that type of instruction in that cycle; a cycle is “spent” on a  stall if the processor could not complete an instruction in that cycle because of a  stall.


Problems in this exercise also assume that individual pipeline stages have the    following latency and energy consumption. The stage expends this energy in order 
to do its work within the given latency. Note that no energy is spent in the MEM  stage during a cycle in which there is no memory access. Similarly, no energy is  spent in the WB stage in a cycle in which there is no register write. In several of  the following problems, we make assumptions about how energy consumption  changes if a stage performs its work slower or faster than this.


4.39.1 [10] <4.14> What is the performance (in instructions per second)?


4.39.2 [10] <4.14> What is the power dissipated in watts (joules per second)?


4.39.3 [10] <4.6, 4.14> Which pipeline stages can you slow down and by how  much, without affecting the clock cycle time?


4.39.4 [20] <4.6, 4.14> It is often possible to sacrifice some speed in a circuit in  order to reduce its energy consumption. Assume that we can reduce energy consumption by a factor of X (new energy is 1/X times the old energy) when we increase  the latency by a factor of X (new latency is X times the old latency). Using this    tradeoff, we can adjust latencies of pipeline stages to minimize energy  consumption  without sacrificing any performance. Repeat 4.39.2 for this adjusted processor.


4.39.5 [10] <4.6, 4.14> Repeat 4.39.4, but this time the goal is to minimize energy  spent per instruction while increasing the clock cycle time by no more than 10%.


4.39.6 [10] <4.6, 4.14> Repeat 4.39.5, but now assume that energy consumption  is reduced by a factor of X2 when latency is made X times longer. What are the  power savings compared to what you computed for 4.39.2?